LLM Tokenization Explained: How Language Models Split Your Text Into Tokens
How tokenizers turn text into IDs, word vs character vs subword tokenization, how byte-pair encoding builds a vocabulary, why tokens shape prompt limits
How tokenizers turn text into IDs, word vs character vs subword tokenization, how byte-pair encoding builds a vocabulary, why tokens shape prompt limits
What the training, validation and test sets each do, how to choose random, stratified, grouped or time-based splits, when to use cross-validation, and
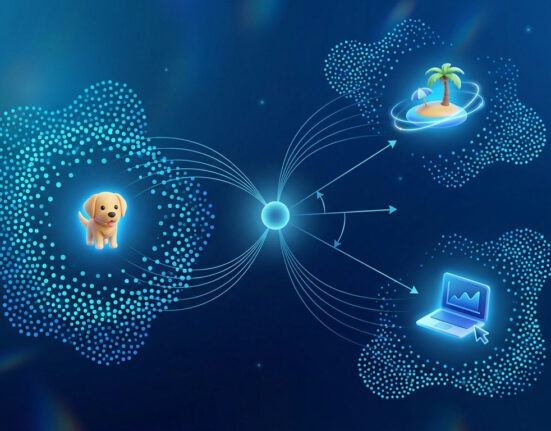
What vector embeddings are, why they replaced one-hot encoding, static vs contextual embeddings, a cosine similarity example you can check by hand, and
What model cards are, the research behind them, a seven-section outline, how Hugging Face README model cards work, a short worked example, and
Dwork and Roth define differential privacy as a definition. Machine learning is a later application in the monograph, not a badge and not
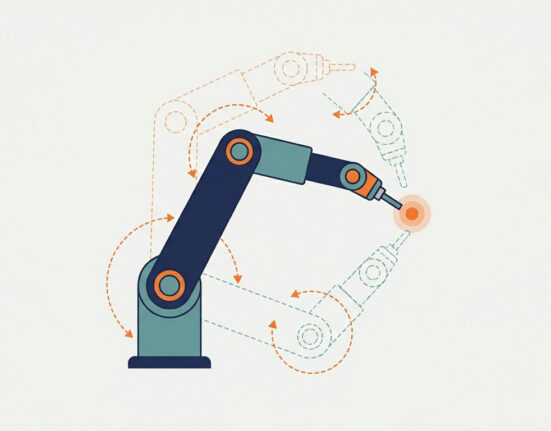
Forward vs inverse kinematics in plain language, a two-joint arm solved by hand, analytical vs numerical solvers, and the joint limits, singularities and
NIST defines cloud computing in SP 800-145 and, later, edge computing as the end-device layer. Neither document defines an edge AI product.
How image data augmentation works, the geometric and colour transforms worth using, automatic policies, how to apply them in TensorFlow and PyTorch, and
What demographic parity, equalized odds and equal opportunity measure, how to choose between them, a four-step fairness assessment with Fairlearn, and the judgement
The search phrase covers three jobs: a prompt, a pretrained model in the browser, and a real training run. This note keeps them