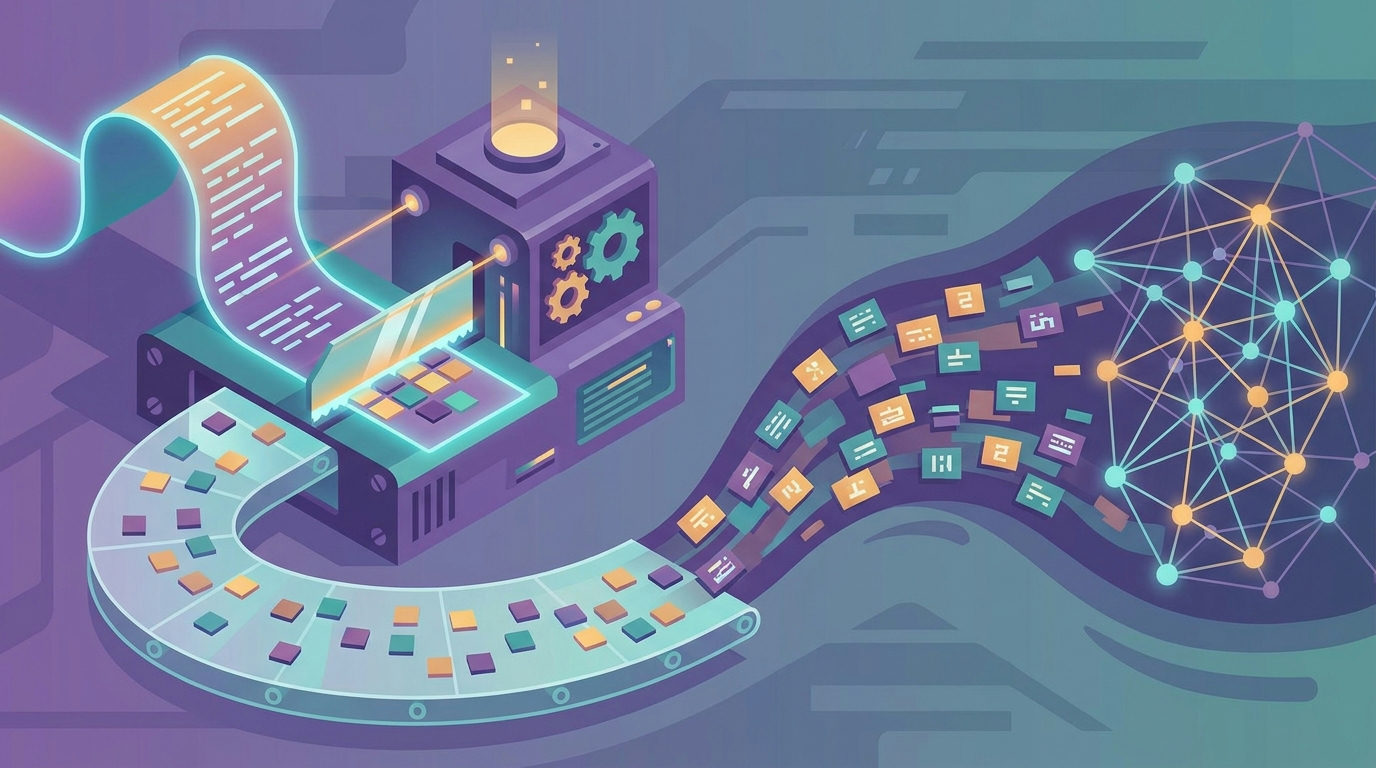
LLM tokenization is the step where a large language model breaks your text into small pieces, called tokens, and turns each piece into a number it can process. Every prompt you type and every reply you read passes through a tokenizer first. Understanding how it works explains several everyday puzzles: why prompt length limits are counted in tokens rather than words, why some text uses up more tokens than other text of the same length, and why models occasionally stumble on spelling or counting letters. This guide explains LLM tokenization in plain language and gives practical tips for working with it.
What a tokenizer does
A model cannot read letters directly. It works with numbers. Hugging Face’s course chapter on tokenizers describes encoding as a two-step process: first the text is split into tokens, then each token is converted to a numerical ID using the tokenizer’s vocabulary. Decoding runs the other way, turning a sequence of IDs back into readable text. The same chapter notes that a tokenizer is saved and loaded alongside its model, because the model only understands the specific vocabulary it was trained with.
Three ways to split text
Word-based tokenization
The obvious approach is to split on spaces and punctuation, giving one token per word. The Hugging Face course explains the drawbacks: vocabularies become very large, related words such as “dog” and “dogs” start out as unrelated tokens, and any word missing from the vocabulary becomes an “unknown” token, losing its meaning entirely.
Character-based tokenization
At the other extreme, you can treat every character as a token. The vocabulary becomes tiny and unknown tokens almost disappear, but sequences get very long, and each individual token carries little meaning on its own.
Subword tokenization
Subword methods sit between the two. The course states the principle: frequently used words should not be split into smaller pieces, but rare words should be broken into meaningful subwords. Its example is “annoyingly”, which can become “annoying” plus “ly”. Common words stay whole, unusual words are built from familiar parts, and the vocabulary stays manageable.
How byte-pair encoding builds a vocabulary
One widely used subword method is byte-pair encoding (BPE). Hugging Face’s BPE chapter describes the training process step by step:
- Start with a base vocabulary of the individual characters found in the training text.
- Count every pair of adjacent tokens across the text.
- Merge the most frequent pair into a new token and add it to the vocabulary.
- Repeat until the vocabulary reaches the chosen size.
Over many merges, common character pairs grow into common syllables, then whole common words. The course lists GPT, GPT-2, RoBERTa, BART and DeBERTa among the models that use BPE. It also explains a variant called byte-level BPE, used by the GPT-2 and RoBERTa tokenizers, which works on bytes rather than characters. Because every piece of text can be expressed in bytes, the course explains, the base vocabulary stays small and no character, including an emoji, has to fall back to an unknown token.
Why LLM tokenization matters in practice
Length limits are counted in tokens
Because a model reads tokens, any limit on how much text it can take in is really a limit on tokens rather than on words or characters. A short common word may be a single token, while a long or unusual word may be several. If a prompt runs out of room sooner than you expected, counting its tokens is the first thing to check.
Not all text tokenizes equally
The BPE process described above builds its vocabulary from whatever text it is trained on, merging the pairs that appear most often. It follows that words common in that training text can end up as single tokens, while words that were rare in it, such as specialist jargon or unusual names, are more likely to be split into several pieces. The same idea of meaning can therefore take a different number of tokens depending on the words used, which is worth measuring for your own content.
Spelling and counting can be awkward for models
A model sees tokens, not individual letters. If a word is stored as one or two tokens, the model has no direct view of its spelling, which helps explain why tasks such as reversing a word or counting a particular letter can trip it up.
Whitespace and formatting count too
Spaces, line breaks and punctuation all become tokens or parts of tokens. Heavy formatting, long tables and repeated boilerplate in a prompt use up space that could hold useful content.
A worked example of LLM tokenization
Imagine a short support message: “My smartwatch won’t sync after the update.” A subword tokenizer would likely keep common words such as “My”, “after” and “the” as single tokens. “Smartwatch” might split into “smart” and “watch”. The contraction “won’t” may be split around the apostrophe, and the full stop becomes its own token. Each piece is then looked up in the vocabulary and replaced by an ID number, and that sequence of numbers is what the model actually reads.
The exact split depends on the tokenizer, which is why two models can count the same sentence differently. The reliable way to know is to run the text through the specific tokenizer you are using.
Where tokenization fits in the bigger picture
Tokenization is only the first stage of what happens to your text inside a language model. A simplified view of the full journey looks like this:
- Tokenize: the text is split into tokens and each token is mapped to an ID.
- Embed: each ID is turned into a vector of numbers, an embedding, that the model can work with. Google’s Machine Learning Crash Course explains embeddings as lower-dimensional representations in which similar items sit closer together.
- Process: the model’s layers combine the token vectors, taking their order and context into account.
- Predict: the model produces scores for which token is likely to come next, and one is chosen.
- Decode: the chosen token IDs are turned back into text, one piece at a time, until the reply is complete.
Seeing the pipeline end to end makes one point clear: the model never handles raw characters. Everything it reads and writes passes through the same vocabulary, so the tokenizer quietly shapes what the model finds easy or hard.
Practical tips for working with tokens
- Check token counts with the right tokenizer. Use the tokenizer that ships with your model, for example by loading it with
from_pretrained()in the Hugging Facetransformerslibrary, and count tokens on real samples of your text. - Trim what the model does not need. Remove repeated headers, navigation text and unnecessary formatting from documents before sending them.
- Chunk long documents by tokens, not characters. If you split text for retrieval or summarisation, measure chunk size in tokens so chunks fit predictably.
- Test multilingual content separately. If you serve several languages, measure token counts for each rather than assuming one figure fits all.
- Do not mix tokenizers and models. A tokenizer from one model family produces IDs another model will misread.
- Give letter-level tasks to code. For exact spelling checks, character counts or string manipulation, a few lines of ordinary code are more dependable than asking the model.
For more on how language models represent meaning after tokenization, see our machine learning hub. If your product serves users in several languages, the AI ethics and bias hub covers ways to check that quality holds up across groups.
Key takeaways
LLM tokenization splits text into tokens and maps each one to a number before a model can read it. Many language models use subword methods such as byte-pair encoding, which keep common words whole and build rare words from smaller parts. Tokens, not words, set the limits on how much text fits in a prompt, and the same length of text can use very different numbers of tokens. Count tokens with your model’s own tokenizer, trim unneeded text, chunk by tokens, and hand exact letter-level tasks to ordinary code.
Written by the TechZone AI Editorial desk.
Leave feedback about this