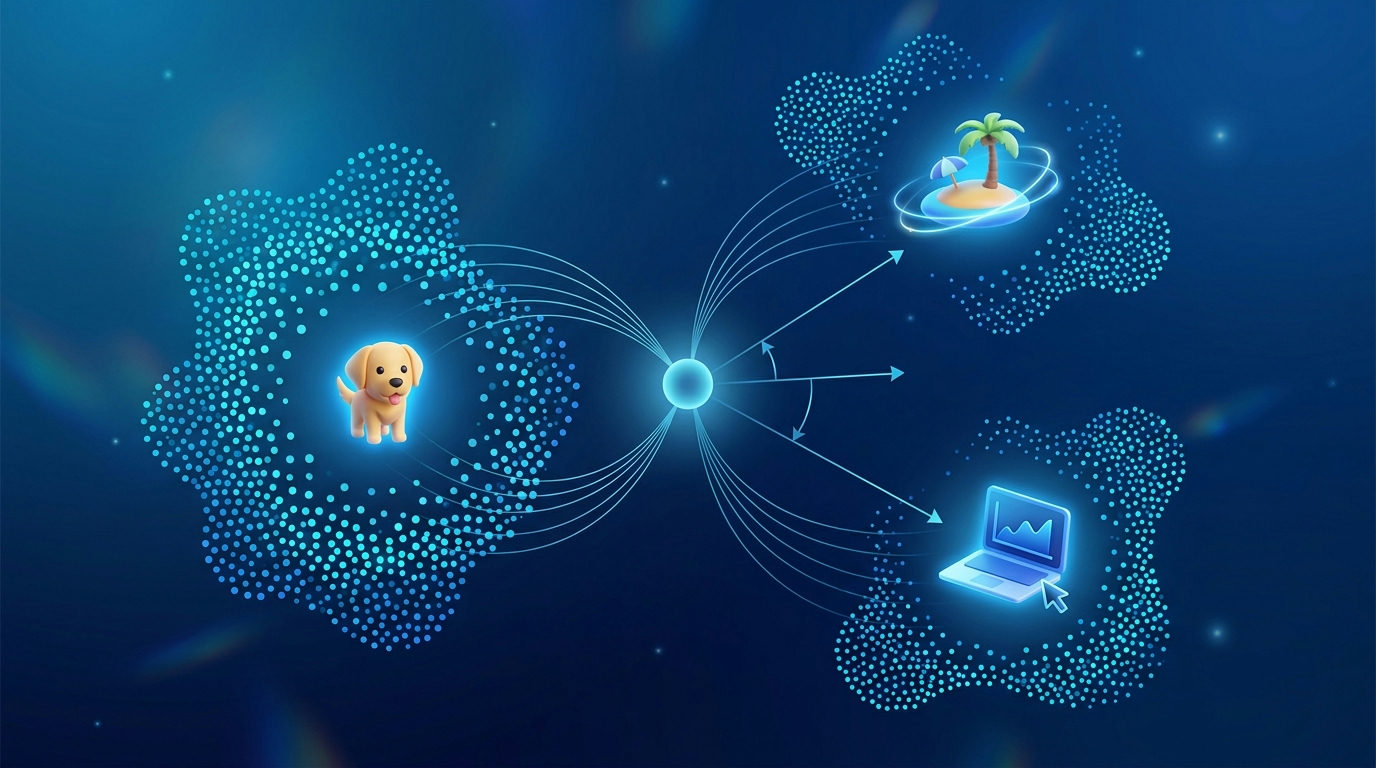
Vector embeddings are lists of numbers that represent words, sentences, images or products in a way a computer can compare by meaning. Items that are similar end up close together, so “puppy” sits near “dog” and a photo of a beach sits near other beach photos. Embeddings are used for semantic search, recommendations, clustering and the retrieval step in AI assistants. This guide explains what vector embeddings are, how they are created, how similarity is measured, and how to use them well in a real project.
Why computers need vector embeddings
Machine learning models work with numbers, so every word or item has to be turned into numbers somehow. The simplest method is one-hot encoding: give each item its own position in a long vector, set that position to 1 and everything else to 0.
Google’s Machine Learning Crash Course explains why that breaks down. With thousands of items, each vector has thousands of dimensions that are almost all zeros, which increases the number of model weights and the data, computation and memory needed. Worse, one-hot vectors carry no sense of similarity. The course’s example: a hot dog is more like a shawarma than a salad, but one-hot vectors treat all three as equally different.
Embeddings fix both problems. The course describes them as lower-dimensional representations of sparse data, where similar items sit closer together in the embedding space.
What a vector embedding looks like
An embedding is a dense vector: a list of decimal numbers, usually far shorter than a one-hot vector for the same items. No single number means anything on its own; the meaning lives in the position of the whole vector relative to others. You can picture a map where cities that are close in real life sit close on the map. Embeddings build a similar map, but for meaning, and with many more dimensions than two.
Because the vectors live in the same space, you can do useful arithmetic with them:
- Compare two items by measuring the distance or angle between their vectors.
- Search for the items nearest to a query vector.
- Group items by clustering vectors that sit close together.
- Average several vectors to represent a group, such as all the products a customer has viewed.
How vector embeddings are created
Embeddings are learned from data rather than written by hand. A model is trained on a task where understanding similarity helps, and the embedding is a by-product of that training.
Static word embeddings
A widely cited early example is word2vec, described in the paper Efficient Estimation of Word Representations in Vector Space — see the paper itself for the authors’ own description of what it proposed and found, rather than a secondhand summary. In a static embedding like this, each word gets one fixed vector, whatever sentence it appears in.
Contextual embeddings
Static embeddings struggle with words that have several meanings. Google’s guide to obtaining embeddings notes that in a static embedding each word is a single point in vector space, even though it may have several meanings, and that contextual embeddings let a word be represented by multiple embeddings that take the surrounding words into account. The course names BERT, ELMo and transformer models as examples. Sentence-level embedding models apply the same idea to whole sentences or passages, which is what semantic search over documents needs.
Embeddings beyond text
The same idea can be applied to other kinds of data. Google’s course, for example, uses a food recommendation task rather than words to show how a neural network can learn an embedding layer, with dimensions that end up loosely tracking qualities such as how sandwich-like or dessert-like a dish is.
Measuring similarity between vectors
Once you have vectors, you need a way to say how close two of them are. The three common choices are:
- Cosine similarity: measures the angle between two vectors, ignoring their length. Scikit-learn’s documentation defines it as the L2-normalised dot product of two vectors. A value near 1 means they point the same way.
- Dot product: multiplies the vectors element by element and sums the result. When vectors are already normalised to length 1, it gives the same ranking as cosine similarity, a point the scikit-learn documentation makes about normalised vectors.
- Euclidean distance: the straight-line distance between two points. Smaller means more similar.
Check the embedding model’s documentation for the similarity measure it recommends before choosing one.
A tiny worked example
Picture three simplified, made-up vectors in a toy three-dimensional space: one pointing in a certain direction, a second pointing in that exact same direction but scaled to be longer, and a third pointing in a completely different direction. Cosine similarity, which only cares about direction, treats the first two vectors as identical in meaning even though one is much longer — because it ignores length entirely. The third vector, pointing a different way, comes out as unrelated to the first two under cosine similarity. Euclidean distance, which cares about both direction and length, tells a different story: it can put the “different direction” vector about as far from the first vector as the “same direction, scaled up” one is, simply because the scaled-up vector is physically farther away in the space. This toy example only exists to build intuition about why direction-based and distance-based measures can disagree — real embedding models and their similarity scores should always be judged on your own data, not on a simplified illustration like this one.
Where vector embeddings are used
- Semantic search: find documents that match the meaning of a query, even when they share no keywords. A search for “laptop won’t turn on” can match an article titled “Fixing a computer that fails to boot”.
- Retrieval for AI assistants: embed a question, find the closest passages in a knowledge base, and give them to a language model as context.
- Recommendations: suggest items whose vectors sit near the ones a user already liked.
- Deduplication: spot near-identical support tickets, product listings or articles by finding pairs with very high similarity.
- Clustering and topic discovery: group thousands of customer comments into themes without labelling them first.
How to use vector embeddings in a project
- Pick one embedding model and stick with it. Vectors from two different models are not designed to be compared with each other. If you change models, re-embed everything.
- Prepare the text. Remove boilerplate, split long documents into passages, and keep useful metadata such as titles and dates alongside each vector.
- Store vectors where you can search them. For small collections, a simple array and a brute-force similarity search is fine. For large ones, use a vector database or a search engine with approximate nearest-neighbour indexing.
- Test with real queries. Write a list of questions your users ask, check the top results by hand, and note where the matches are wrong.
- Combine with keywords where it helps. Embeddings can blur exact identifiers like product codes. Google Cloud’s retrieval guide describes hybrid search, which combines semantic and keyword search, as one way to handle this.
Limitations to keep in mind
- Embeddings learn from their training data. If that data has gaps or skewed patterns, the vectors can carry them too. Check results for sensitive queries before launch; our AI ethics and bias hub covers practical audit methods.
- Similarity is not truth. A close match means “related”, not “correct”. Downstream systems still need checks.
- Domain language matters. General-purpose models may miss specialist vocabulary. Test on your own content before committing.
For more on the models that produce embeddings and how they are trained, see our machine learning hub.
Key takeaways
Vector embeddings turn words, documents, images and other items into dense lists of numbers placed so that similar things sit close together. They are a compact alternative to sparse one-hot encodings, capture meaning, and make semantic search, recommendations and retrieval possible. Choose one embedding model, measure similarity with the metric its documentation recommends, test results against real queries, and remember that a close vector signals relatedness, not accuracy.
Written by the TechZone AI Editorial desk.
Leave feedback about this