A train validation test split divides your data into three parts so you can build a model on one, tune it on another and judge it honestly on a third. It sounds like housekeeping, but it is the step that decides whether your evaluation numbers mean anything. Get it wrong and a model can look excellent in testing, then disappoint as soon as it meets real data. This guide explains what each set is for, how to split data for different situations, and the leakage mistakes that quietly inflate results.
Why you cannot test on training data
The scikit-learn guide to cross-validation puts it directly: learning a model’s parameters and testing it on the same data is a methodological mistake. A model that simply repeated the labels of the examples it had seen would get a perfect score and still fail on anything new. That gap between memorising and generalising is called overfitting, and a separate evaluation set is how you detect it.
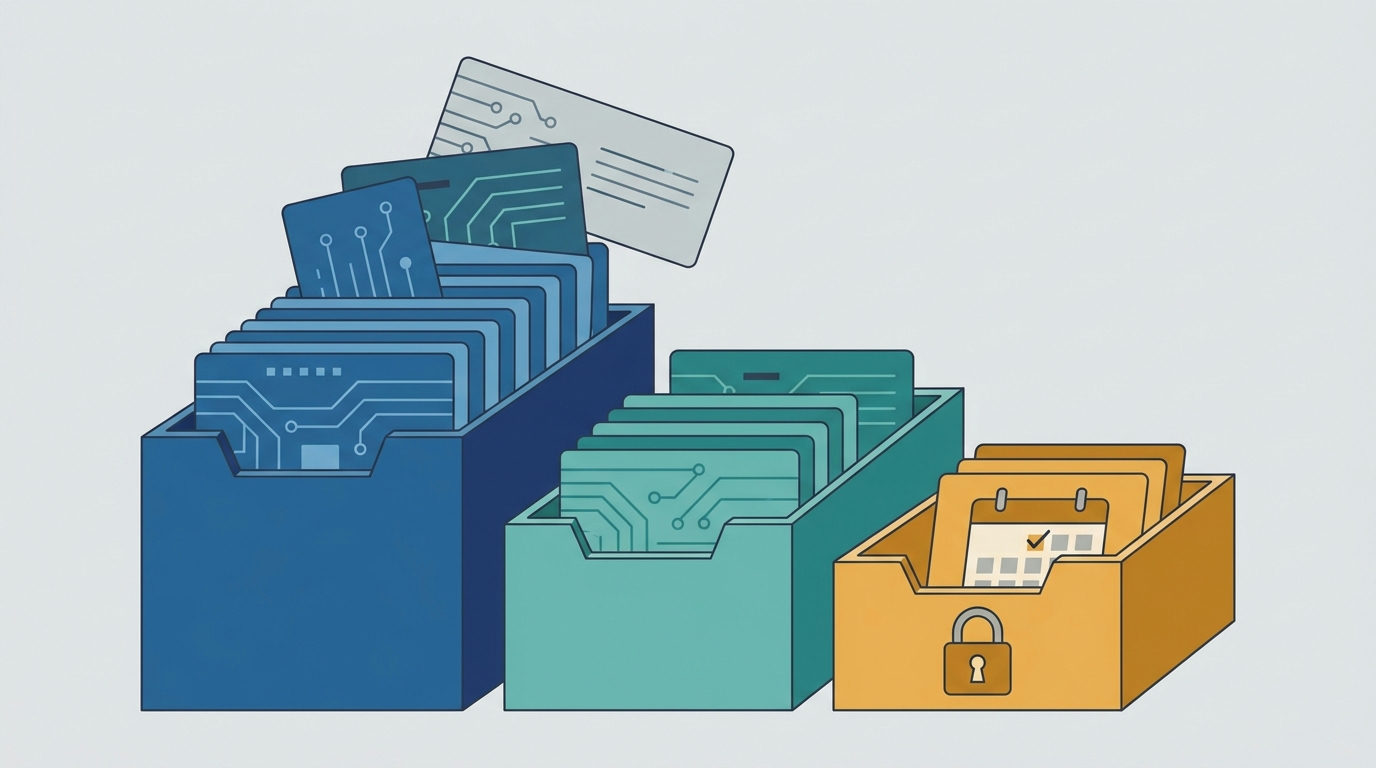
What each part of a train validation test split does
- Training set: the data the model learns from. Its weights or rules are fitted here.
- Validation set: data used during development to compare models, choose settings (hyperparameters) and decide when to stop training.
- Test set: data held back until the end and used to estimate how the finished model will perform on new examples.
Why three sets rather than two? Scikit-learn explains that when you tune settings by checking results on the test set, knowledge about the test set can leak into the model, and the evaluation stops reporting true generalisation performance. A validation set absorbs that tuning, so the test set stays untouched.
How big should each set be?
There is no universal rule, but Google’s Machine Learning Crash Course uses a split of roughly 70% training, 15% validation and 15% test as its example. The more important guidance on the same page is about quality rather than proportions. A good test set should be large enough to give meaningful results, represent the data as a whole, contain no duplicates of training examples, and reflect the conditions the model will face in use.
In practice:
- With plenty of data, you can afford generous validation and test sets.
- With limited data, use cross-validation (below) instead of a single fixed validation set, so every example contributes to both training and evaluation.
- Whatever the sizes, make sure rare classes appear in every set in sensible numbers.
Choosing the right splitting method
Random split
For independent examples, such as separate product reviews, a random split is usually fine. In scikit-learn, train_test_split does this in one line. Set a random_state so the split is reproducible.
Stratified split
If one class is rare, a random split might put very few of its examples in the test set. Stratified splitting keeps class proportions consistent. Scikit-learn’s guide describes StratifiedKFold as returning folds in which each set contains approximately the same percentage of samples of each class as the complete set, and train_test_split accepts a stratify argument for the same purpose.
Group split
Sometimes several examples belong together: many photos of the same product, several sessions from the same user, or repeated readings from the same machine. If members of one group land in both training and test sets, the model can recognise the group rather than learn the task. Scikit-learn’s GroupKFold ensures the same group is not represented in both testing and training sets.
Time-based split
For data collected over time, such as sales or sensor readings, a random split lets the model peek at the future. Train on earlier data and test on later data instead. Scikit-learn’s TimeSeriesSplit builds successive training sets that grow forward in time, each followed by a later test period.
Cross-validation when data is limited
K-fold cross-validation splits the training data into k parts. As scikit-learn describes it, the model is trained on k−1 of the parts and validated on the remaining one, and the process repeats so each part takes a turn as the validation fold. You then average the results. This gives a more stable estimate than a single validation set and uses your data more efficiently. Keep a separate test set aside for the final check even when you use cross-validation for tuning.
Data leakage: the mistakes that inflate results
Leakage happens when information from outside the training set sneaks into training. These are the common forms:
- Preprocessing on the full dataset. Scikit-learn stresses that steps such as standardisation and feature selection should be learned from the training set and then applied to held-out data. Fitting a scaler on all your data before splitting lets test-set statistics shape training.
- Duplicates across sets. Google’s course gives a spam-filter example in which test results looked unrealistically strong because the test set contained duplicates of training emails. De-duplicate before you split.
- Related examples split apart. Use group-based splitting when examples share a source.
- Future information. Features that would not be known at prediction time, such as a “refund issued” flag when predicting refunds, make a model look far better than it can be.
- Tuning on the test set. Every time you look at the test score and adjust the model, the test set becomes less trustworthy.
The cleanest defence against preprocessing leakage is a pipeline. Scikit-learn’s Pipeline chains preprocessing and the model so that, during cross-validation, each preprocessing step is fitted only on the training folds.
A worked example of a train validation test split
Suppose you are building a model that predicts which customers will cancel a subscription next month. Each customer has many monthly records, and you have several years of history. A careless approach would shuffle every monthly record and split at random. That mixes the same customer into training and test data, and it lets the model learn from later months while being tested on earlier ones.
A better train validation test split for this problem works in two directions at once:
- By time: train on the oldest periods, validate on the next period, and test on the most recent one, so evaluation mirrors predicting the future.
- By customer: within those periods, keep each customer’s records in only one set, so the model cannot score well simply by recognising a familiar account.
The test score from this setup may well look less impressive than a random split would. That is the point: it is a more realistic preview of how the model will behave after launch.
A practical splitting checklist
- Remove exact and near-duplicate examples before doing anything else.
- Decide what counts as independent. If examples share a user, device, product or time period, split by that unit.
- Split off the test set first and do not look at it again until the end.
- Use stratification if any class is rare.
- Put all preprocessing inside a pipeline so it is fitted on training data only.
- Tune with a validation set or cross-validation, never with the test set.
- Report the final test score once, alongside how the split was made.
- Refresh evaluation data over time. Google’s course notes that the more you reuse the same data for decisions, the less confidence you can have in predictions on new data.
For related guides on model evaluation and overfitting, visit our machine learning hub. If your model makes decisions about people, also check results by group; our AI ethics and bias hub explains how.
Key takeaways
A train validation test split gives each part of your data one job: training fits the model, validation guides choices, and the test set gives a final, honest estimate. Pick the splitting method that matches how your data was generated, whether that is random, stratified, grouped or time-based. Remove duplicates, keep preprocessing inside a pipeline, tune without touching the test set, and refresh your evaluation data as the real world changes.
Written by the TechZone AI Editorial desk.
Leave feedback about this