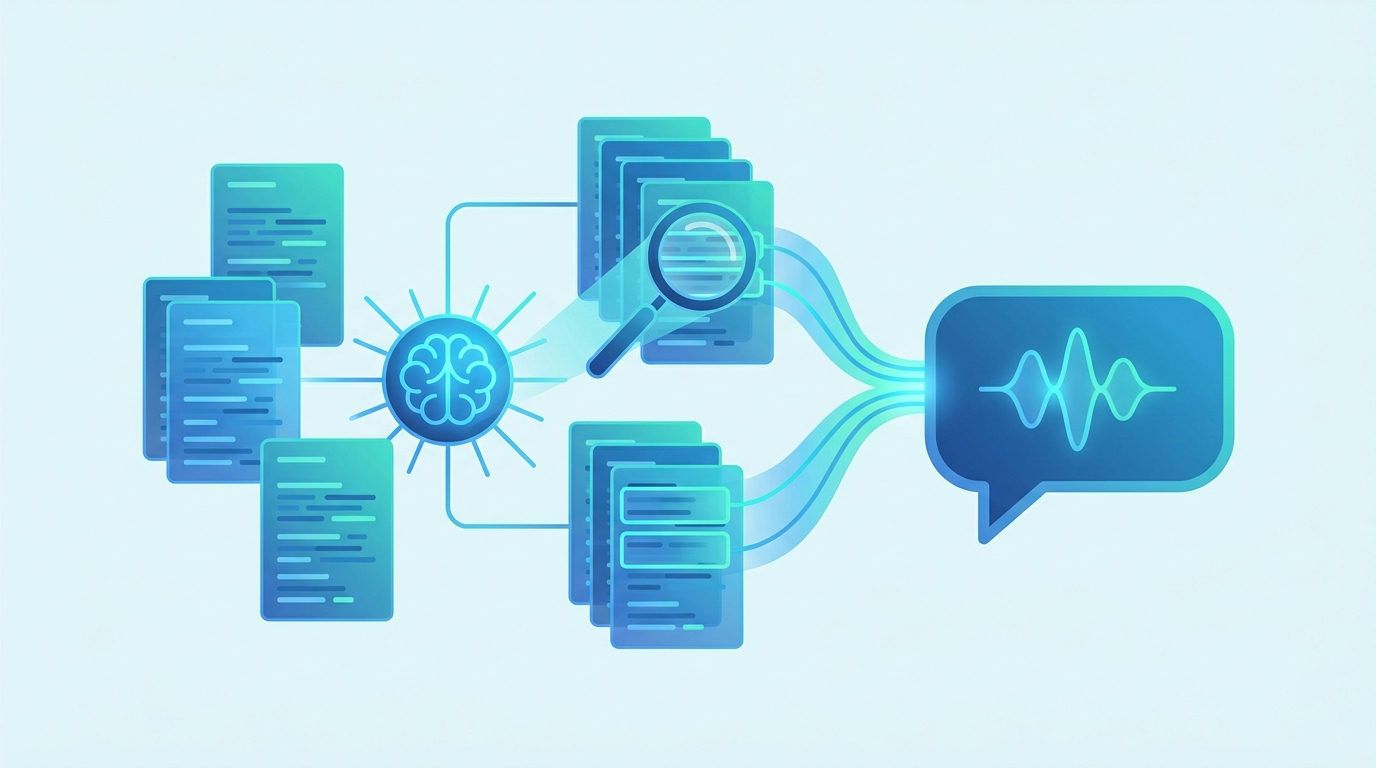
Retrieval augmented generation, usually shortened to RAG, is a way of making a language model answer from documents you choose instead of from memory alone. Before the model writes anything, a search step pulls the most relevant passages from your own knowledge base and places them in the prompt. The model then writes its answer with that evidence in front of it. This guide explains how the pieces fit together, where RAG tends to break, and how to build and test a first version without overcomplicating it.
What retrieval augmented generation actually is
The term comes from a 2020 research paper by Patrick Lewis and colleagues, Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. The authors describe two kinds of memory. The first is parametric memory: everything a pre-trained model has absorbed into its weights during training. The second is non-parametric memory: an external index of documents that a retriever can search at question time. In the paper, that external memory was a dense vector index of Wikipedia, and the authors note that it gives the system knowledge that can be inspected and updated without retraining the model.
That split is the whole idea. A model’s weights are expensive to change and hard to audit. A document index is cheap to change and easy to audit. RAG lets the model handle language, reasoning and tone, while the index handles facts.
Why teams reach for RAG
Most teams arrive at RAG because a plain chatbot keeps giving confident answers about things it cannot know: last month’s policy change, an internal product code, or a support article written after the model was trained. Google Cloud’s overview of RAG lists the usual motivations: answers based on fresher information than the model’s training data, responses grounded in supplied facts, and fewer invented details as a result.
There are practical benefits too:
- Citations become possible. Because you know which passages were retrieved, you can show the reader where an answer came from.
- Updates are a re-index, not a retrain. Edit a document, re-embed it, and the next answer can reflect the change.
- Access control stays in your hands. You can filter what each user is allowed to retrieve before the model ever sees it.
How a retrieval augmented generation pipeline works
Every RAG system, from a weekend prototype to an enterprise assistant, follows the same basic flow. It splits into an offline indexing stage and an online question-answering stage.
1. Collect and clean your documents
Start with the sources you actually trust: help-centre articles, product manuals, policy documents or wiki pages. Strip navigation menus, cookie banners and repeated footers. Boilerplate that appears on every page will otherwise match almost every query and crowd out the useful text.
2. Split documents into chunks
Models and retrievers work better with focused passages than with whole files. Split each document into chunks of a few paragraphs, and keep each chunk’s title and section heading attached as metadata. A small overlap between neighbouring chunks helps when an answer straddles a boundary. Google’s guide mentions chunking strategy as one of the things to adjust when improving results.
3. Turn chunks into embeddings
An embedding model converts each chunk into a vector, a list of numbers that places text with similar meaning close together. Store the vectors, the original text and the metadata in a vector database or a search index that supports vector queries.
4. Retrieve the best matches for each question
When a user asks something, embed the question with the same model and look up the nearest chunks. Many production systems combine this semantic search with ordinary keyword search, which Google describes as hybrid search. Keyword matching catches exact terms such as error codes and product names that embeddings can blur.
5. Re-rank and trim
A re-ranker scores the retrieved candidates again with a more careful model and keeps only the strongest few. This step matters more than it sounds: passing ten loosely related chunks to the model often produces a worse answer than passing three strong ones.
6. Generate a grounded answer
Finally, build a prompt that contains the user’s question, the selected chunks and clear instructions, for example: answer only from the sources provided, say so when the sources do not contain the answer, and cite the source title for each claim. The model writes the response from that context.
Where RAG systems usually go wrong
When a RAG assistant gives a bad answer, the cause is usually retrieval rather than the language model. These are the failure points worth checking first:
- The answer was never in the index. No amount of prompt tuning fixes a missing document. Log the questions that get “I don’t know” responses and treat them as a content backlog.
- Chunks are too large or too small. Large chunks dilute the relevant sentence; tiny chunks lose the context that explains it. Test two or three sizes on the same question set.
- Stale or duplicate versions. If an old policy and a new one are both indexed, the retriever may return the wrong one. Remove superseded documents or store a version date and filter on it.
- Exact identifiers get missed. Pure vector search can struggle with part numbers or acronyms. Hybrid search usually helps.
- The prompt allows guessing. If the instructions do not tell the model to stay within the sources, it may fill gaps from its general training.
RAG or fine-tuning?
People often ask whether they should fine-tune a model instead. The two solve different problems. Fine-tuning changes how a model behaves: its format, tone or skill at a narrow task. RAG changes what a model can see at the moment it answers. If your problem is “the model does not know our facts” or “our facts change every week”, RAG is usually the better first step. If your problem is “the model knows enough but answers in the wrong style or structure”, fine-tuning may be worth exploring. Many mature systems use both.
For more background on how models learn and why they sometimes memorise the wrong patterns, see our machine learning hub.
How to evaluate retrieval augmented generation
Evaluate the two halves separately, because a single “was the answer good?” score hides where the problem is.
- Build a test set. Write 30 to 50 real questions your users ask, and for each one note which document should answer it.
- Measure retrieval. For each question, check whether the correct chunk appears in the top results. If it does not, fix chunking, metadata or search settings before touching the prompt.
- Measure groundedness. Read the generated answers and mark any statement that is not supported by the retrieved text. Google Cloud’s evaluation tooling, described in the same overview, scores generated text for qualities such as groundedness and question-answering quality.
- Check refusals. Include questions your documents cannot answer. A well-behaved system should say it does not have that information rather than improvise.
- Re-run after every change. Keep the test set fixed so you can compare versions honestly.
A simple starter architecture
If you are building a first prototype, keep it small enough to understand end to end:
- One document source, such as a folder of help articles exported as text.
- A chunker that splits on headings, then on paragraphs, with a short overlap.
- One embedding model and one vector store, used for both indexing and querying.
- Top-k retrieval followed by a lightweight re-ranker that keeps three to five chunks.
- A prompt template that requires citations and allows “I don’t know”.
- A logging table that records each question, the retrieved chunk IDs and the final answer.
That log is the most valuable part. It shows you which documents are doing the work, which questions fail, and where your knowledge base has gaps.
Responsible use
Retrieval augmented generation reduces invented answers but does not remove them, and it can surface whatever is in your index, including outdated or sensitive material. Review what goes into the index, respect document permissions at retrieval time, and keep a human review step for answers that affect customers or money. Our AI ethics and bias hub covers practical ways to audit automated systems before they reach users.
Key takeaways
Retrieval augmented generation pairs a language model with a searchable document index so answers can be grounded in sources you control. Most of the quality comes from the retrieval side: clean documents, sensible chunks, hybrid search and a re-ranker. Test retrieval and generation separately with a fixed question set, require citations, and let the system admit when it does not know. Start small, log everything, and let the failed questions tell you what to fix next.
Written by the TechZone AI Editorial desk.
Leave feedback about this